Removing burned-in text from four real clips: our test notes
We burned captions, stickers and a prop into four Pexels clips, then removed them with our own pipeline. What worked, what failed first, and the limits.
EraseVideo AI · Published
How did we test?
All four clips are Pexels-licensed stock footage. None of them came with text on them. We burned the text overlays in ourselves (subtitles, a caption, a title card and a badge), then removed them with our own pipeline, the same one that runs on the site. The fourth clip tests an object instead of text.
That is the method, and it shapes how to read these notes. Because we added the text, we had the clean source to compare against instead of judging by eye. It also means we chose the footage, so your clips may behave differently. The limits section at the end says where we expect that.
Clip 1: subtitles over a busy night street
Source: Shinjuku street at night, by Tianwang Xiao. 1080p, 20 seconds.
We burned in 4 subtitle lines, each changing every 5 seconds, then rendered on the HD tier. The video was cut into 4 segments, and all 480 of 480 frames were rebuilt.
Results:
- Outside the mask, almost nothing changed. The average change was under 2/255. The rebuilt area is pasted back into your original frames, so the rest of the picture is your original.
- No visible jump at the segment seams. Neighbouring segments crossfade over 8 frames.
- The neon signs were left alone. The scene is full of lit signs with sharp lettering, and none of them were touched, because none of them were ticked.
What went wrong the first time
This clip was the hardest for detection, and early versions got it wrong in three ways.
- Neon signs and map labels were boxed as subtitles. They have sharp edges, which is what the detector looked for. We now also require a box's brightness to stay stable across the frames we sample. Subtitles hold steady; flickering signs do not.
- One caption was split into three boxes. We now merge fragments that sit on the same row.
- The preview looked like a failure when it wasn't. The default preview frame once landed on the exact moment one subtitle line was swapping for the next, so it showed half-rebuilt text. The preview now picks a frame well inside a subtitle's time range.
If a preview frame of yours looks odd, check whether it sits on a subtitle change before you judge the result.
Clip 2: a caption across a face
Source: a talking-head video by ANTONI SHKRABA production, portrait, 480×854.
We placed a caption across the face at mouth height, a hard spot because the mouth moves on every word and viewers look straight at it. We rendered this one in HD.
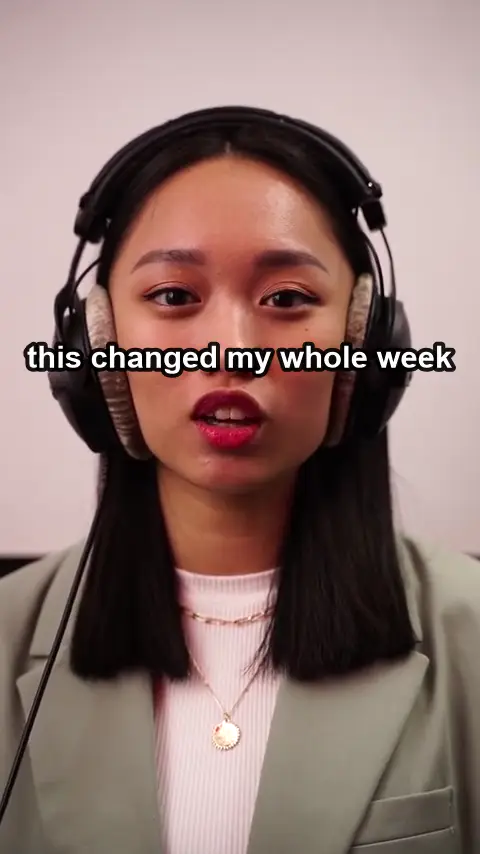
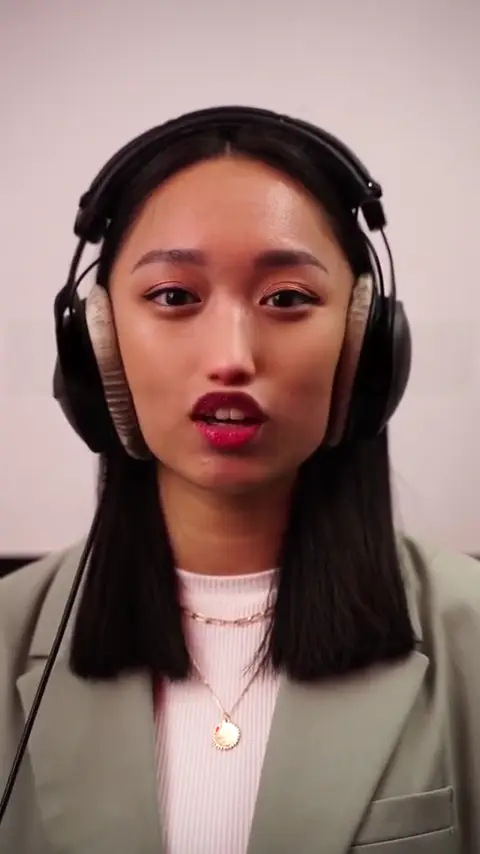
Faces are the reason HD exists. Standard rebuilds the masked area at 480p, and over skin, lips and hair that can look soft. HD rebuilds at 720p. If your captions cross faces, run the free preview on a frame where the caption covers the mouth, and choose HD if Standard looks smudged.
Clip 3: a title card and a sticker, with a sign we kept
Source: a market stall by bizarreaudio, portrait.
We added a "SATURDAY MARKET HAUL" title card and a pink "TODAY" badge. The stall also has a hand-painted "MANGOSTEEN" sign that belongs to the scene.
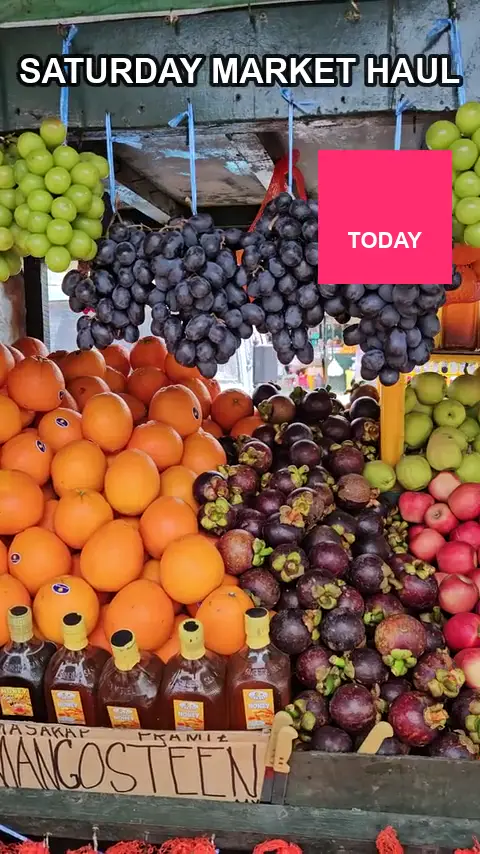
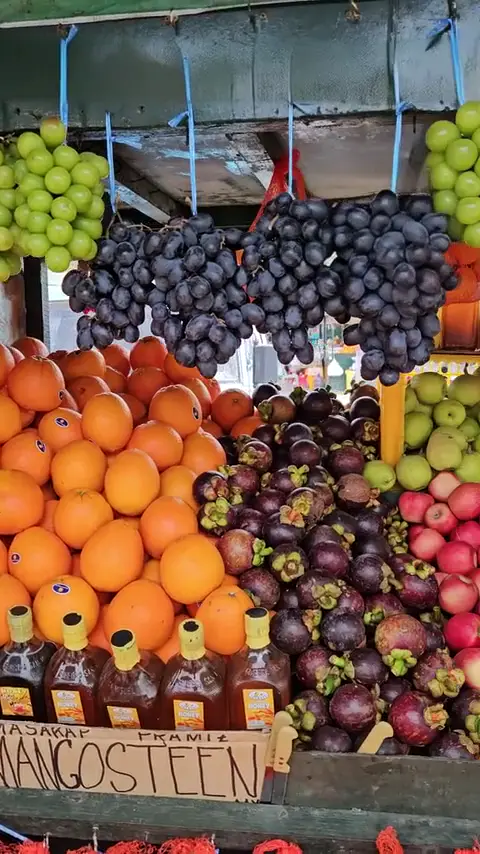
We deliberately left the sign alone. Nothing is removed unless its box is ticked, so text that belongs to the scene stays.
Clip 4: an object in a moving shot
Source: a moving gym shot.
Here the target was not text but a wooden box, removed with an object box. An object box rebuilds everything inside it, so it should be a little larger than the object, shadow included.
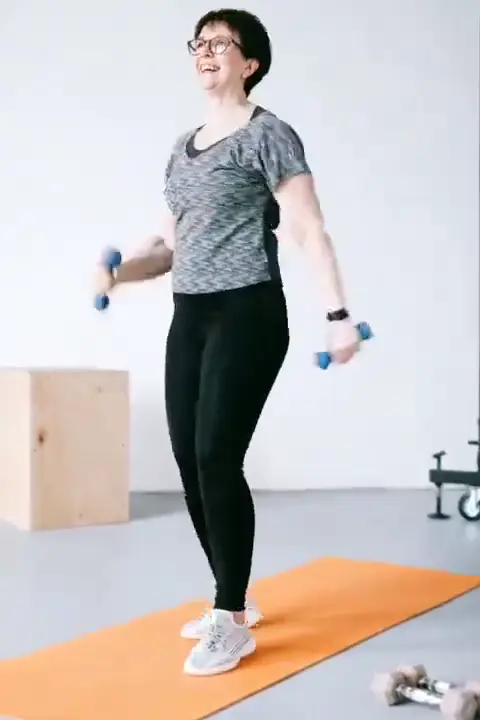
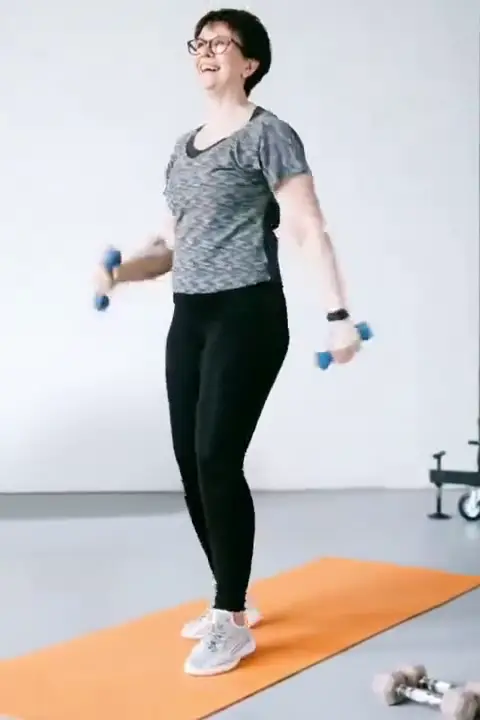
When the background behind an object shows up in other frames, the fill has real picture to borrow from. That is the condition object removal depends on.
How precise is a text mask?
A text box rebuilds only the letters and their outline, and keeps the rest of the box as it was. On our test, the letter mask covered about 97% of the true text pixels. A few pixels of padding around the letters catch the rest.
How long does a render take, and what does it cost?
An end-to-end Standard render of a 6-second clip cost 6 credits and took about 105 seconds, from clicking render to the file being ready. Standard is 1 credit per second and HD is 3. The one-frame preview is free and needs no account.
Limits we saw or expect
- Fast motion over background that is never revealed can smear. The fill borrows from nearby frames. If the area behind the text is never visible, there is nothing to borrow.
- Faces and hair look soft in Standard. Use HD for these.
- A face covered for the whole clip cannot be recovered. If a caption hides the same face from the first frame to the last, the fill is invented. It may look plausible, but it is not the person's real face.
Try it on your own clip
- Remove subtitles from video for captions and burned-in subtitles.
- Remove objects from video for props, clutter and logos.
- Remove emoji and stickers from video for overlays you added yourself.